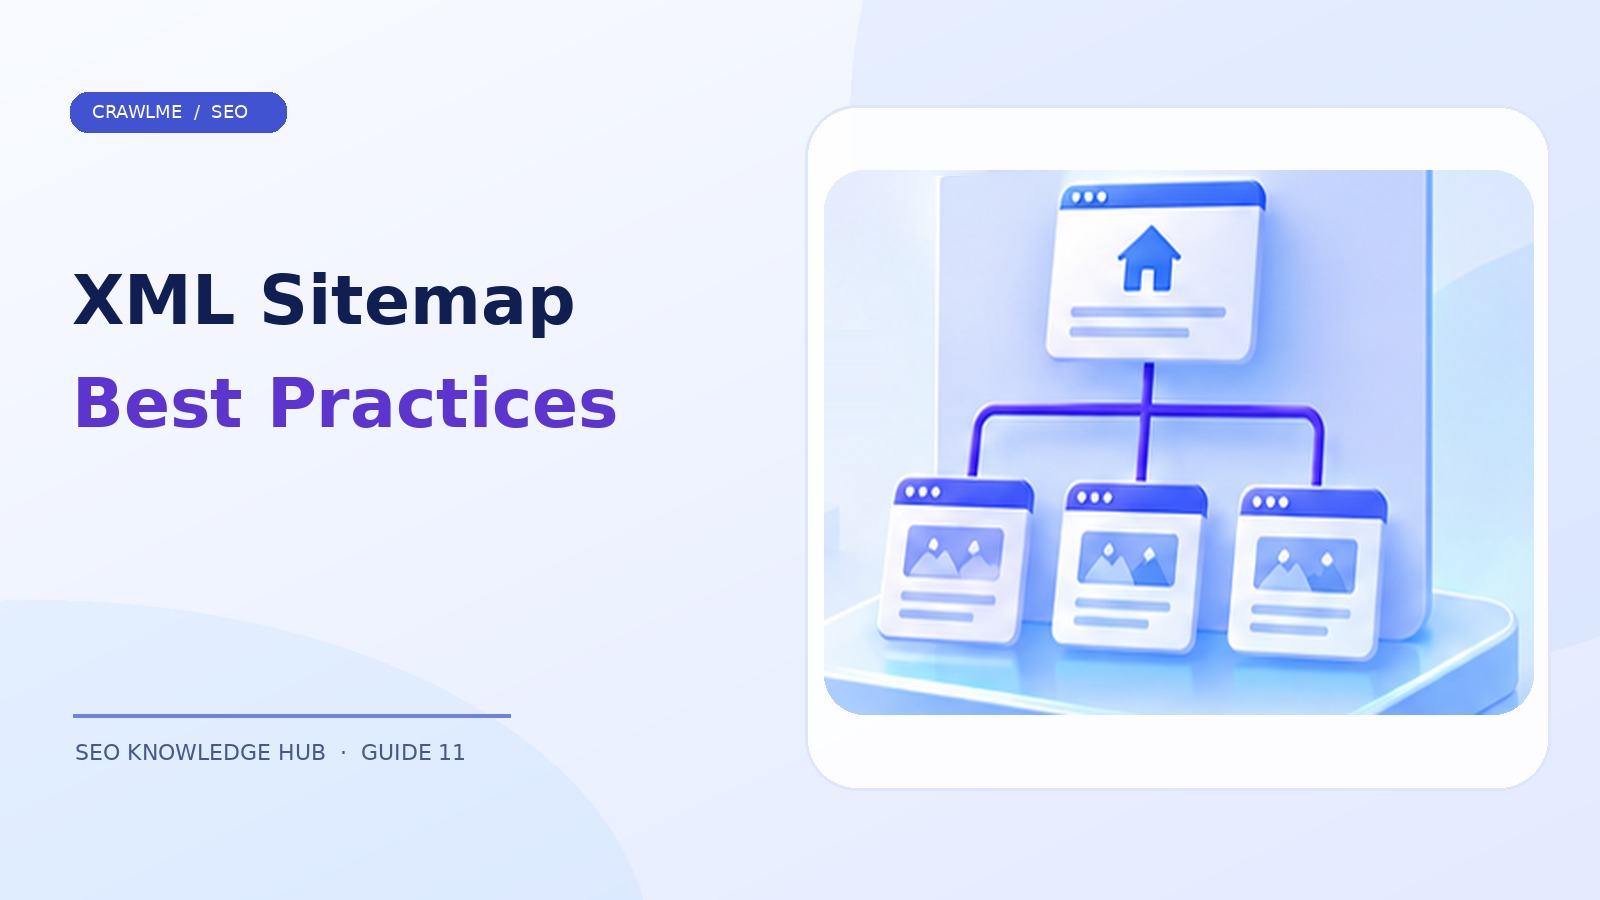
An XML sitemap is a discovery aid: it tells search engines which URLs you consider important, particularly when a website is large, new, or difficult to navigate. It does not override a noindex directive, force Google to crawl a URL, or guarantee indexing. A clean sitemap is therefore less about increasing the URL count and more about supplying an accurate, maintainable inventory.
1. Decide which URLs deserve to be in the sitemap#
Start with pages intended to appear in Google Search: canonical articles, product pages, indexable categories, and other substantive public URLs. Exclude login screens, internal search results, staging environments, URLs blocked by noindex, redirects, deleted pages, and duplicate query-parameter versions. A URL technically can be in a sitemap while excluded from indexing; doing so produces noise rather than an actionable discovery list.
Compare your sitemap against your CMS's actual published state. A common defect is a product importer that adds an item to sitemap.xml before the product page is publicly reachable. Another is a deleted article that remains in a cached sitemap. Your publishing pipeline should update the sitemap only after the destination page is live and eligible.
2. Use valid XML and absolute URLs#
A minimal sitemap looks like this:
<?xml version="1.0" encoding="UTF-8"?>
<urlset xmlns="http://www.sitemaps.org/schemas/sitemap/0.9">
  <url>
    <loc>https://example.com/guides/clean-url/</loc>
    <lastmod>2026-11-01</lastmod>
  </url>
</urlset>
Use fully qualified, properly escaped URLs. Keep host, protocol, trailing-slash convention, and URL casing consistent with your preferred canonical addresses. XML characters such as & must be escaped as & in URL values. Test the actual downloaded file with an XML parser rather than judging from how the browser displays it.
Google supports standard sitemap limits of 50,000 URLs or 50 MB uncompressed per sitemap. Use a sitemap index and multiple files beyond those limits. Compression with .gz can reduce transfer size but does not remove the uncompressed size limit.
3. Make lastmod truthful#
Google can use <lastmod> when it is consistently and verifiably accurate. Set it when the page's substantive content changes: for example, revised instructions, a corrected specification, or materially updated product details. Do not set every page's timestamp to the current day just because the sitemap was regenerated or a footer year changed. False freshness signals reduce the utility of the field.
If your CMS cannot track meaningful modifications reliably, omit lastmod rather than fabricate updates. Google ignores <priority> and <changefreq> values, so do not spend development time tuning them as if they were ranking controls.
4. Split large sitemaps along operational boundaries#
A site with thousands of URLs might use /sitemaps/products-1.xml, /sitemaps/categories.xml, and /sitemaps/articles.xml referenced by /sitemap-index.xml. Segmentation makes debugging easier: when a product import breaks, you can isolate the affected sitemap without reprocessing the entire site inventory.
Do not create hundreds of tiny files without a reason. Choose stable segmentation based on category, URL count, or content type, then automate updates. Make sure each sitemap file is accessible to the crawler and that the sitemap index references only existing files.
5. Submit and monitor in Search Console#
In your verified Google Search Console property, open Sitemaps, submit the sitemap or index URL, and review its fetch and parsing status. A successful submission confirms processing of the sitemap file, not indexing of every included URL. Use the Page indexing report and URL Inspection to investigate individual URLs.
A useful weekly review compares four lists: CMS pages intended to be indexed; URLs in sitemaps; pages returning 200 and declaring the correct canonical; and Google's indexed or excluded pages. Differences reveal stale publishing jobs, canonical conflicts, and accidental exclusions.
6. Troubleshoot the right layer#
Could not fetch: Request the sitemap URL directly. Check DNS, TLS, redirects, authentication, firewall rules, and response status. Confirm the file is not HTML disguised as XML.
XML parsing error: Validate encoding, namespace declarations, escaped characters, and tag closure. A single unescaped & can invalidate the document.
Submitted URL has noindex: Decide whether the page should be indexed. Remove the directive if it is a public page worth indexing, or remove the URL from the sitemap if exclusion is intentional.
Duplicate or alternate canonical: Check whether the sitemap URL differs from the declared or Google-selected canonical. Align internal links, redirects, canonical tags, and sitemap entries.
Many discovered but uncrawled URLs: Do not assume the sitemap is broken. Check internal navigation, server responsiveness, newly generated low-value URLs, and crawl trends.
7. Make sitemap maintenance part of the publishing workflow#
For a content site, regenerate relevant sitemap entries when posts are published, updated, redirected, or deleted. For an e-commerce catalogue, coordinate sitemap updates with product availability and canonical product URL logic. In a multi-tenant platform, enforce each tenant's allowed hostnames; accidentally mixing other domains into the wrong sitemap creates confusing signals.
For a fast quality check, download the sitemap and sample 20 URLs across content types. Verify their HTTP response, noindex, canonical tag, and presence in site navigation. This catches more meaningful problems than simply counting entries.
Example: an automated product import pipeline#
Suppose a store imports 600 products every night. The importer writes database rows, image processing runs asynchronously, and the storefront only publishes products after validation. If the sitemap uses the database creation timestamp, search engines may discover unfinished pages that show temporary placeholders. A safer workflow marks each product draft, processing, or published and generates sitemap entries only for published, public, canonical URLs. When a product is removed, the sitemap is updated alongside its redirect or 404 policy.
A useful acceptance test takes 25 randomly chosen sitemap URLs and checks whether each returns a complete page, the expected canonical, and an indexable robots state. Run this after publishing-pipeline changes. It does not prove that Google indexed the pages, but it establishes that the sitemap accurately represents what your site offers.
How to interpret mismatched counts#
If the sitemap includes 10,000 URLs but Search Console reports a smaller indexed count, first determine whether the difference is expected. Some pages may be new, duplicate, intentionally excluded, or not selected for indexing. Group non-indexed URLs by reason and template, then sample a few examples in each group. A total alone cannot diagnose a cause. Conversely, some URLs indexed by Google may have been discovered through links and may not appear in the sitemap. The sitemap is not a complete accounting of Google's index.
What to measure each month#
Track sitemap fetch health, canonical consistency, the number of eligible live URLs missing from the sitemap, and the number of stale or non-indexable URLs still included. For new editorial content, also measure the elapsed time from publication to the first verified Googlebot crawl using logs where available. Do not confuse that time with time to indexing: they are distinct events.
Where CrawlMe fits#
CrawlMe can complement the maintenance process when a team needs to organize URL submissions or process batches after publishing. It does not replace XML sitemaps, internal links, Search Console, or Google's independent indexing decisions. Fix the sitemap and destination-page eligibility first; then use CrawlMe if bulk submission management is useful for your workflow.
Final checklist#
- Every URL is public, intentional, and canonical.
- XML is valid; URL values are escaped and absolute.
- Each file respects the published sitemap limits.
-
lastmodreflects significant page updates. - Sitemap index entries resolve successfully.
- Search Console reports no unresolved sitemap processing issue.
- A sample of pages is tested beyond their presence in the sitemap.
Frequently asked questions#
Does a sitemap guarantee indexing?#
No. A sitemap helps discovery. Google decides whether and when to crawl and index individual URLs.
Should I include redirected URLs?#
Generally no. Include the final canonical destinations and update links and redirects consistently.
How often should I resubmit my sitemap?#
Normally submit the stable sitemap URL once, then keep its contents accurate. Repeatedly submitting an unchanged file does not force recrawling.